SILENT FAILURE MAPPING FOR AI CHAT AGENTS

Your AI agent didn't throw an error.That's the problem.

A request can succeed while the answer is wrong. Your agent sounds confident and your monitoring stays green. I find those failures, investigate the causes and rank what to fix first.

For startups and SMEs with a chat agent live in their product. $1,500 audit, completed in 5 business days.
A LOOK INSIDE THE AUDIT

From confident answer to clear finding.

AUDIT WALKTHROUGH
WHAT YOUR CUSTOMER SEES
Customer

Does the Starter plan include SSO?

Your agent

Yes, SSO is included with every plan.

A confident response

A fluent answer can still create the wrong expectation.

WHAT I CHECK01 / 04

It sounds helpful.

Your customer hears a clear “yes”. But confidence alone does not make the answer correct.

Does the claim hold up?

Check it against the source.

Done-for-you evaluationHuman-reviewed findingsYour team owns the release
THE GAP A GOOD DEMO DOESN’T SHOW

Monitoring stays green.
Your customer sees the wrong answer.

A wrong answer can sound perfectly right.
Your users feel the difference.

01

The answer sounds certain.
The information is wrong.

An invented policy. An unsupported claim. A promise your product cannot keep.

02

The conversation continues.
The context disappears.

Your user repeats themselves while the agent loses the details that matter.

03

The update looks small.
The behavior changes.

A prompt or knowledge change quietly breaks a conversation that worked before.

Most teams treat this as a model problem. They tune the prompt, swap the model, re-chunk the knowledge base and ship again. Nothing improves, because nobody established what was actually breaking. That's not a model problem. That's a testing problem.

Why your team can't catch it

  1. 01

    The people who wrote the prompts judge the answers, and unknowingly ask questions it can answer.

  2. 02

    There is no written definition of “correct” to test against.

  3. 03

    Doing it properly takes someone who has done it before.

  4. 04

    Testing tools still leave you to write the tests, define correct and read the output.

THE REPORT YOUR TEAM RECEIVES

Scattered issues.
Clear causes.

I group related failures by cause and rank what to fix by business impact. I separate confirmed causes from suspected ones.

HOW I TRACE THE CAUSE

For every failure, I ask the question again with the correct information supplied. If the answer improves, I investigate retrieval. If it stays wrong, I investigate the instructions and model. I use the available evidence to confirm the cause or label it suspected. That distinction guides the fix.

Evidence you can inspect

Exact conversations, test conditions, expected behaviour, severity and observed failure frequency.

Causes with confidence labels

Confirmed findings and suspected causes are clearly separated.

Priorities with business context

Improvements ranked by impact, frequency and affected workflows. Effort estimates stay provisional.

A FINISHED RESULT FOR YOUR TEAM

Every AI testing toolsells you a gym.I show up and lift.

01TestReal conversations
02VerifyReviewed evidence
03PrioritizeYour next fixes

A tool still leaves your team to write the tests, define what correct means, wire it up and interpret the output. I hand you the answers.

Explore my approach
TWO WAYS TO WORK TOGETHER

Start with clarity.
Build on it.

A baseline today.
Ongoing capacity as your product grows.

02Keep it working

Dedicated QA Partner

I handle your QA, without the hire. From testing each release to covering your whole product.

Full month · 22 working days

22 working days a month dedicated to your product, from release regression to full QA coverage.

  • Regression against your baseline on every release
  • Quality testing for any AI feature, not just chat
  • Web, mobile & API functional testing
  • Critical-flow automation & release sign-off
Explore this serviceDiscuss your QA needs

Fixed price, never hourly. Scope agreed in writing before testing.

A SMALL ASK FROM YOUR TEAM

About an hour of
your team's time.

A 30-minute intake, a 30-minute walkthrough. I run everything in between.

See the eight-stage process
01

I get the context

In a 30-minute intake, I learn your agent’s goals, rules and the questions that matter.

02

I test and investigate

I design the tests, review failures and investigate the causes.

03

I walk you through the findings

In 30 minutes, I explain the evidence, priorities and next steps.

THE PERSON BEHIND KUALIMATE

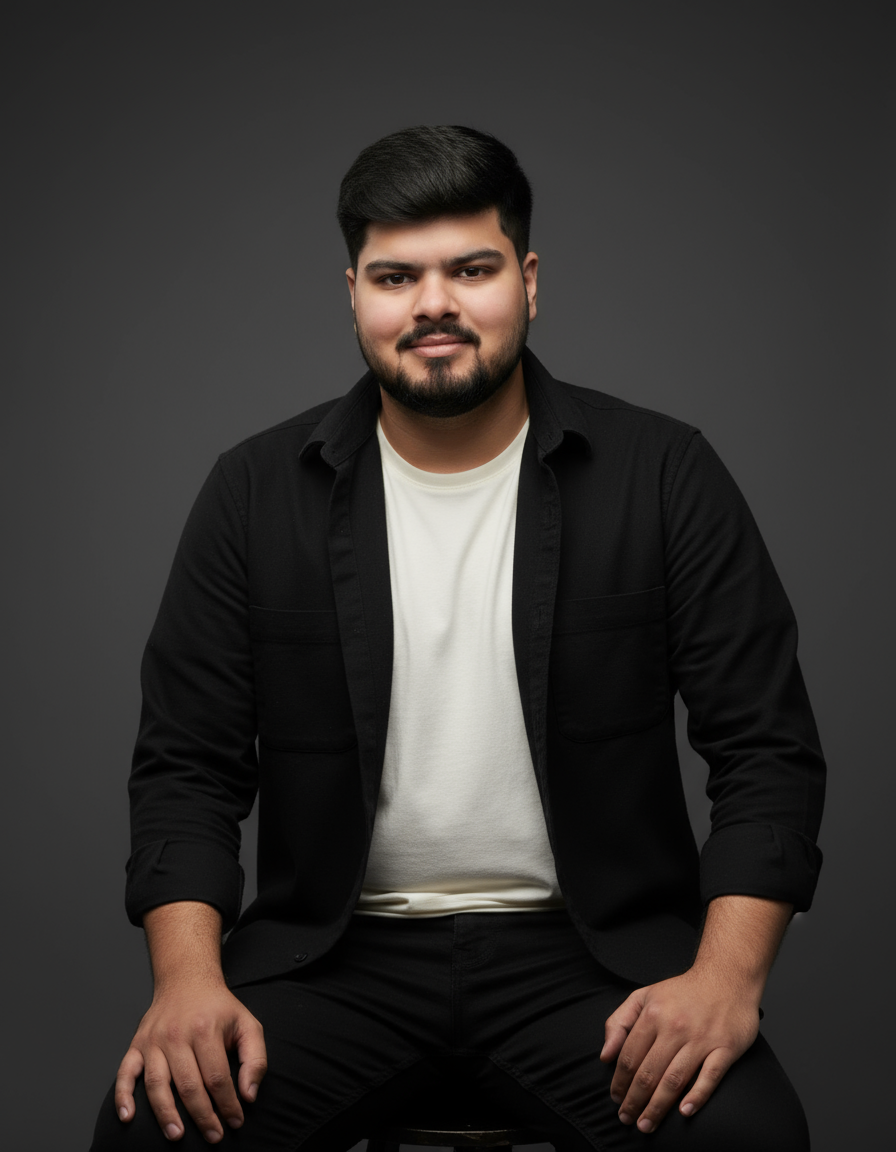
I'm Rana Usman
Shahid.

Senior SDET & AI Quality Engineer

You work directly with me. I design your tests, review every failure and walk your team through the findings.

5+years in quality
engineering

20+ projects
AI · Fintech · E-commerce

Rana Usman Shahid, Senior SDET and AI Quality Engineer behind Kualimate
HUMAN JUDGMENTBehind every finding.

I review every run.

From prior work

1,200+

Prompts evaluated

80+

Hallucination patterns surfaced

78% → 92%

Chatbot accuracy improved

94%

Semantic search relevance across 10,000+ queries

18 months

Zero critical defects on an institutional trading platform

LLM evaluationRAG testingAgent qualityPrompt regression
FAQs

Before I start.

The practical details, answered.

See the audit process